TLDR
A push notification hijack through ASOS's third-party communication platform exposes a testing gap most engineering teams share. Here's how to close it.
At around 10:00 UK time on Tuesday, ASOS customers opened the retailer's app to find a notification they were never meant to see. Headed "ASOS HACKED", it was addressed to the company's DPO and IT team and claimed that attackers had compromised a data platform used by the retailer. It came with a link to a Telegram channel.
By mid-afternoon, ASOS confirmed the incident: the company is investigating "unauthorised activity involving third-party platforms that we use to communicate with customers," has restricted access to the notification platforms, and is working with advisers and authorities. ASOS added that basic personal information may have been accessed, and that it does not believe payment card details or account passwords were affected. Its website and app kept operating normally throughout.
Charlotte Wilson of Check Point described what made this unusual: hackers had "turned ASOS's own app into their ransom note." The message was written for ASOS's internal teams, but customers read it on their lock screens.
That delivery channel, the third-party integration ASOS uses to reach its customers, is where most test suites stop. Testing third-party integrations end-to-end is the gap this incident makes visible.
Your test suite stops where your customers' experience doesn't
Most automated suites verify the code your team wrote. That is the right place to start. But customers don't experience your code, they experience your code plus every integration it calls: the push notification provider, transactional email, SMS platforms, in-app messaging, deep links.
None of those are usually asserted on.
The typical approach mocks the integration boundary: a test triggers a request, a stub returns a success response, the test passes. What the customer actually receives on their lock screen is never verified. Push notification testing is a clear example. The debate in developer communities is whether push flows belong in automated suites or can be left to monitoring. The default answer tends to be neither, which is why incidents like Tuesday's reach engineering teams through customer screenshots.
Prismatic's four-layer integration testing framework is direct on why: sandbox environments are rarely representative of production. Volume, rate limits, authentication configurations, and vendor API versions all differ. The fourth layer, always-on production monitoring, catches the class of failures that unit, contract, and even E2E tests miss.
Push notification flows are testable end-to-end. A documented approach using Firebase Cloud Messaging treats the instrumented test as the app backend: it acquires the push token, triggers the notification via the provider's API, and waits for the app to confirm receipt and verify the message. The flow is automatable. Most teams just haven't done it.
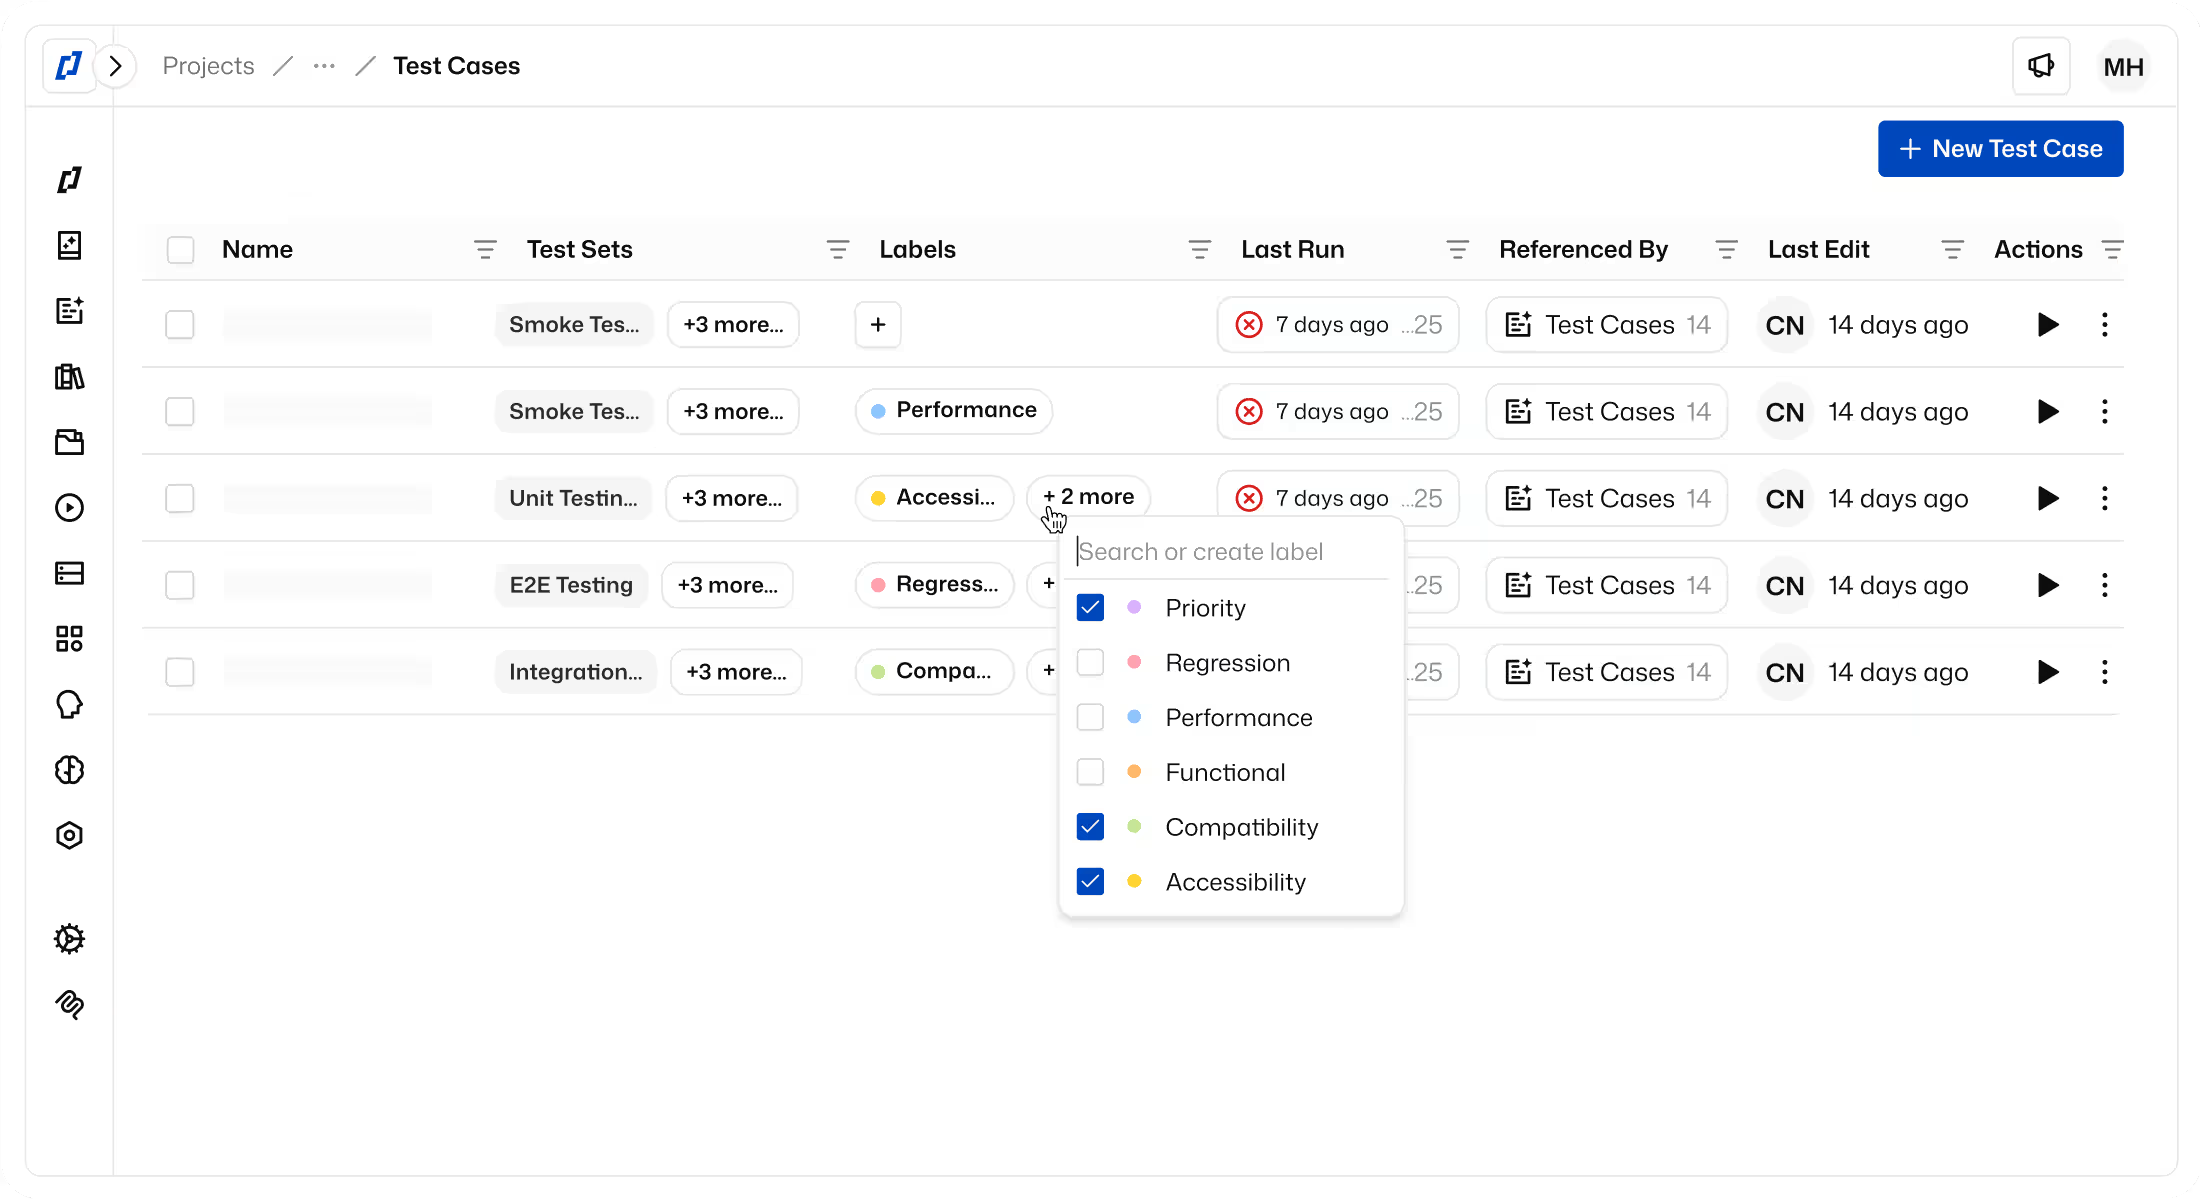
Thunders AI test agents run full user journeys in plain language, including steps that cross third-party service boundaries, rather than stopping at a mocked response. A flow that triggers a notification and then verifies what the app does when it arrives is an end-to-end path you can run in CI.
Testing in staging isn't enough. Watch production
Even a thorough pre-release suite cannot catch what changes in production after you ship.
Vendor APIs update without notice. Authentication configurations drift. A credential rotation touches systems in sequence. The notification service that worked in staging runs on a different configuration in production, different rate limits, different auth chain, sometimes a different provider environment entirely.
Merge.dev is direct on the consequence: "No test suite can fully replicate every real-world configuration. That's why monitoring is as critical as testing." Their approach is continuous monitoring in production, tracking sync health, error patterns, and behavioural changes from third-party APIs, so anomalies surface before customers report them.
For notification flows, the practical version is a scheduled test against production: a seeded account that receives a test notification on a defined schedule, with assertions on sender identity, template content, and any links. If the output changes unexpectedly, an alert fires to Slack or your on-call system. That is detection, not prevention. No monitoring setup stops an attacker who already has credentials. But it shrinks the gap between "it happened" and "we know" from hours to minutes.
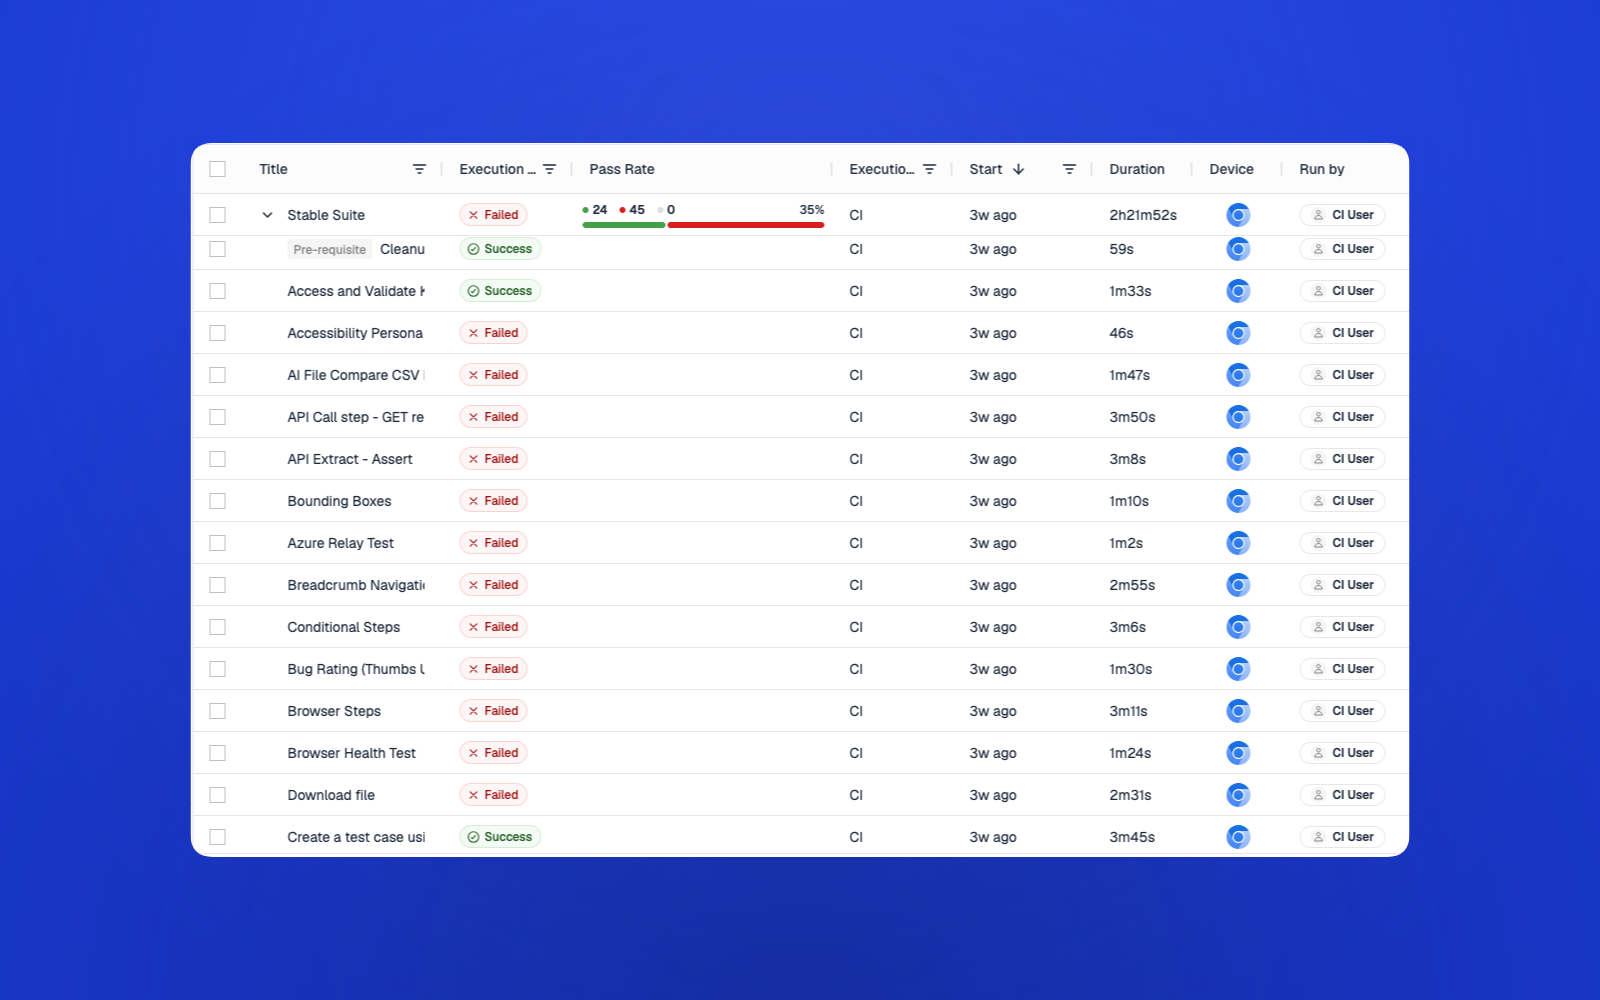
Thunders supports scheduled test set runs. Configured once, running on a recurring schedule against any environment, including production. The Inbox notifies you when a run fails. A simple flow running on a schedule is what turns production monitoring from a principle into a practice.
The second incident: shipping fixes under pressure
Once ASOS confirmed the breach, the response began: credential rotation, vendor access review, configuration changes, emergency patches. Each of those touches customer-facing flows, login, checkout, notification opt-in, password reset, and each ships under time pressure.
This is when regressions slip in. Not from carelessness, but because there is no time to debug a broken selector while rotating credentials under an incident. If your regression suite fails on a UI change during that window, teams either ignore the failures or stop running the suite. Either way, the next patch goes out without a verified regression gate.
The 72 hours after a security incident typically involve credential and token changes, vendor configuration updates, feature flag adjustments, and sometimes a change of notification provider. Every one of those has the potential to silently break a customer flow.
A practical checklist for teams shipping under pressure:
- Re-run login and authentication flows immediately after any credential change
- Verify checkout and payment flows are unaffected by vendor reconfiguration
- Test notification opt-in and opt-out against the updated notification platform
- Run password reset against the new credential state
- Check deep links. They break silently when push provider configurations change
Thunders self-healing tests absorb the selector and configuration changes that would break a traditional suite during a fast-moving incident response: when an element changes, Thunders repairs the selector in the run and logs the fix. With CI/CD integration, every hotfix runs through the same regression gate automatically, on every commit.
Run your first test free or map the integrations your tests currently skip, in 15 minutes.