TLDR
- A UI redesign and a new modal broke 45 of our 69 E2E tests mid-release.
- Noise → init script. One script dismissed the modal for every test, which cleared about 90% of the failures.
- Changed journeys → MCP. One prompt bulk-updated the affected tests, and an engineer fixed 2–3 stragglers by hand.
- Everything else → self-healing. Tests whose elements only moved kept passing.
- Fixed in an hour, and the release shipped on schedule.
We test Thunders with Thunders. Obviously. Thunders is an AI test automation platform, and our own end-to-end suite runs against our own product, as the first step of our daily release. That suite is the last thing standing between a merge and a rollback
Our last release reshuffled our app’s sidebar. The project dropdown, the organization dropdown, user controls, language settings: all reorganized, with several entries moved into a new Configure section. The same release shipped Inbox, announced with a full-screen notification the first time a user opens the app.
On that day the suite went red. Largely red.
We had budgeted for a few broken navigation steps. We had not budgeted for the modal. What follows is the actual repair, in order, and the three things that made it take an hour instead of the rest of the week.
45 of 69 tests, e2e tests failed for one reason
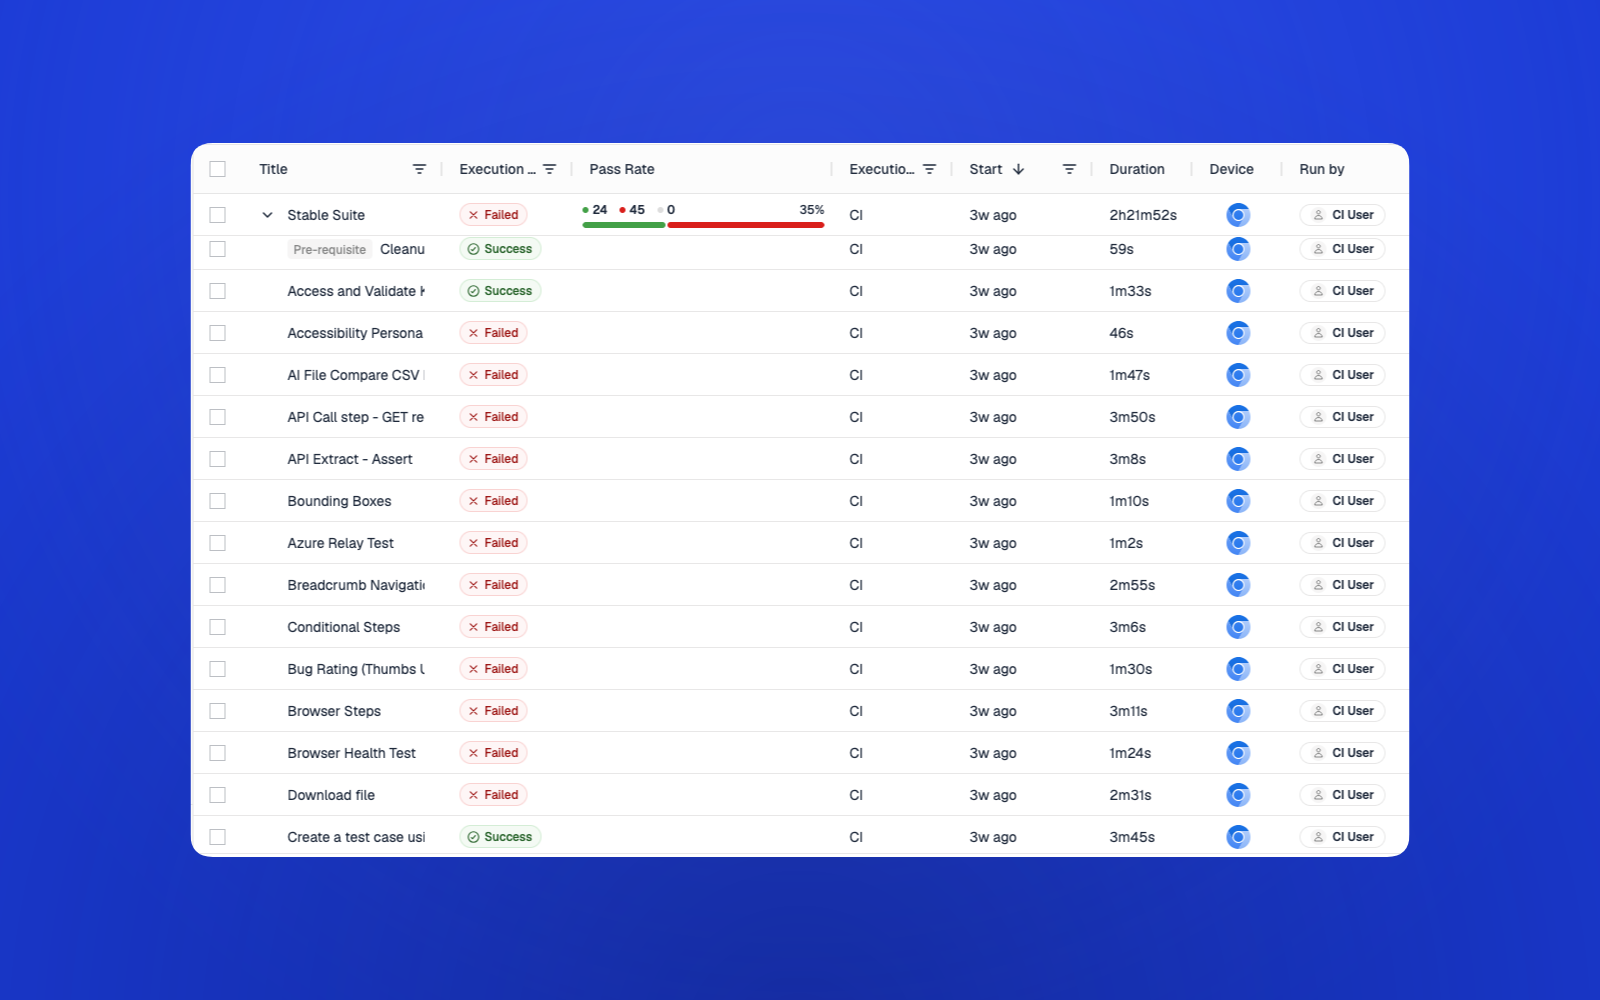
The Inbox announcement sat above the application and blocked interaction with everything underneath it, including the sidebar. Of our 69 end-to-end tests, 45 failed because they reach for the sidebar in their first few steps. And they failed for a reason that had nothing to do with what they were testing.
The obvious fix is the wrong one. Add a "dismiss the notification" step at the top of every test, ship it, move on. That works perfectly. And this is what your favorite LLM would have done to your 45 tests. Put a step into 45 journeys that has no business being in any of them, and when the announcement is retired the step has to come back out of all 45. These accumulate. Six months later nobody remembers which of them are still load-bearing.
Init scripts: fix the environment, not the suite
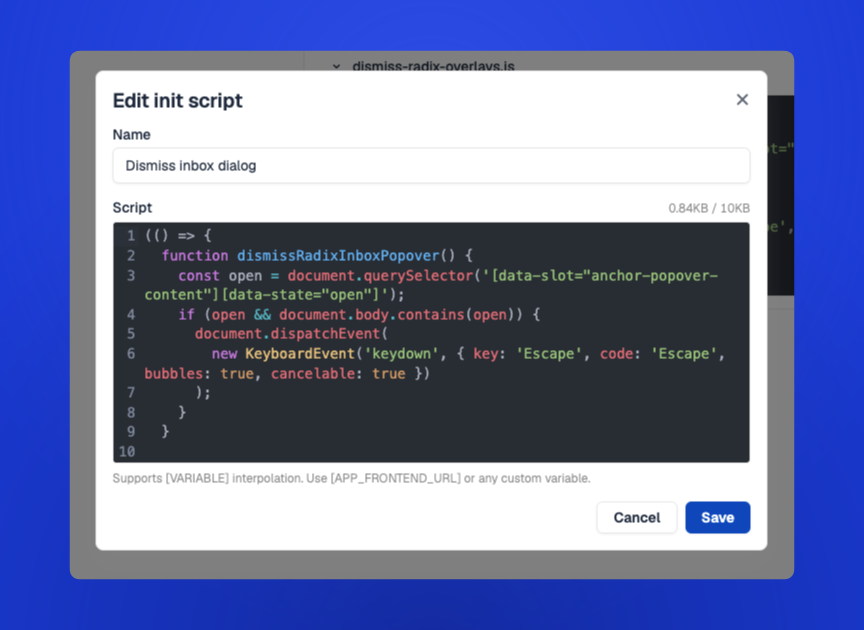
Thunders exposes init script capability: JavaScript injected when the test environment starts, before the page loads. On every run, on every new page, consistently, when it should.
We wrote one that dismisses the Inbox announcement whenever it appears. One script, applied environment-wide, edited directly online : no PR, no one-hour CI, testable immediately. And no test touched. That removed roughly 90% of the failures.
An init script is JavaScript that runs before every page loads, putting the browser in the right state for a test. Configured per environment, it can bypass captchas, set feature flags, disable analytics, or prevent banners and overlays from appearing.
One caution, because this is easy to overuse. An init script is for noise. If a modal is part of the product experience you want to verify, suppressing it hides a real hole in your coverage rather than fixing a broken test. The question worth asking is whether a user would consider the thing part of the journey.
Ours wasn't. An onboarding prompt for a feature we had just shipped is noise for a test about switching projects.
MCP: updating the tests that genuinely changed
Here is the exact prompt we used:
Our sidebar was reorganized in the last release. Switching project is no longer done from the project dropdown — the user now opens the **organization menu**, clicks **Configure**, and picks the project from there.


In project <project-name>:

	1. Pull the latest test run and list every test case that failed on a step involving the organization or project dropdown.

	2. For each of those, read the steps and find where the journey assumes the old navigation (a click on the organization or the project dropdown followed directly by selecting a project).

	3. Update that sequence to the new journey: open the organization menu → click Configure → select the project. Insert the missing Configure step rather than rewriting the whole test, and keep every assertion and every following step untouched.

	4. Don't touch anything else. If a test fails for a different reason, or the steps don't match this pattern, skip it and list it at the end so we fix it by hand.

Before applying anything, show me the list of test cases you'll change with a before/after of the steps, and wait for my go.
Once the modal was out of the way, a small set of tests still failed. These were the real regressions: journeys that had actually moved.
The redesign changed how you switch projects. Instead of selecting a project where the dropdown used to live, you now go through the organization and the new navigation flow first. Some tests clicked the organization and never found the projects they expected.
Those needed real edits, and the edit was the same shape every time: add the navigation step into Configure, then continue to the relocated item. We used the Thunders MCP server to identify the affected tests and apply that update across them in a single prompt, instead of opening each one. Two or three stragglers didn't fit the pattern, and an engineer fixed those by hand.
The division of labour is worth being precise about. The init script handled failures that weren't really failures. The MCP handled the ones that were. Neither tool covers for the other, and reaching for the wrong one is how a one-hour job becomes a three-day job.
Once the modal was out of the way, a small set of tests still failed. These were the real regressions: journeys that had actually moved.
Self-healing tests: why most of the suite never noticed
Given how much of the sidebar moved, we expected a long tail of broken steps. We got a short one.
The core sidebar was still there. Plenty of items stayed where they were. And nothing about the underlying product behaviour changed (switching a project still switched the project). Thunders resolves steps from the intent of the action rather than from a frozen selector, so items that shifted position were still found and the tests carried on.
The tests that needed a human were the ones where the journey itself changed: an item had moved under Configure, so a user now has to do something new to reach it. That is the right dividing line. A test should break when the user's path changes. It should not break because a div moved.
An hour, not a week
The regressions were cleared during the release, in about an hour, and the release shipped on schedule.
When a suite goes red at scale, the instinct is to start opening tests. It is almost always the wrong move. In our case it would have cost days (and we release every day). It would also have left a dismiss step buried in all 45 journeys we own.
Classify the failures first. Anything caused by something outside the journey gets handled once, at the environment level. Anything caused by a changed journey gets bulk-updated. What's left is usually small enough to fix by hand in ten minutes.
Most of the suite doesn't need touching. That's rather the point of having one.